Zero Downtime Migration – Monitor GoldenGate Replication

When you are migrating your Oracle Database with Zero Downtime Migration (ZDM) and the Logical Online method, you are using Oracle GoldenGate to handle the replication. The replication keeps the OCI target database in sync until you can perform the switchover. Thus, it is a vital part of the process. Let’s see how you can monitor the replication.

I have already started a migration which is currently paused at the phase ZDM_MONITOR_GG_LAG.

Monitor Services

Log on to the Oracle GoldenGate Hub via HTTPS. Use the host name, private or public IP address or whatever your network allows.

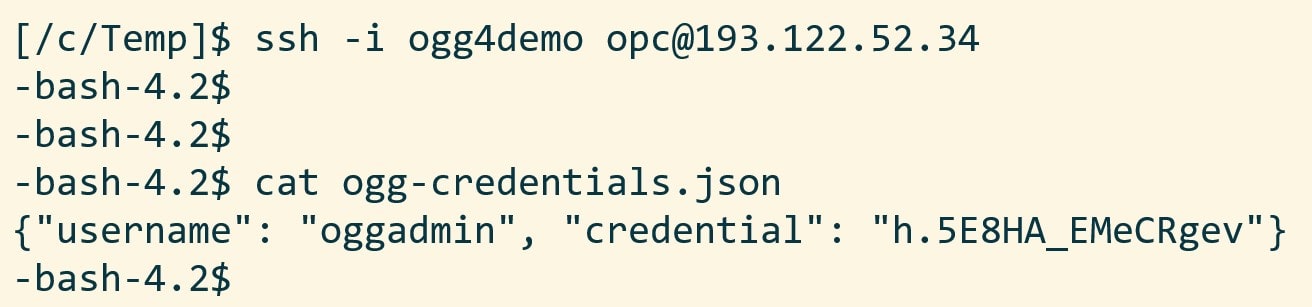
You are prompted for credentials. Log on as oggadmin – in lowercase. The password you can find in the file ogg-credentials.json which you find on GoldenGate Hub. The log in prompt of Oracle GoldenGate

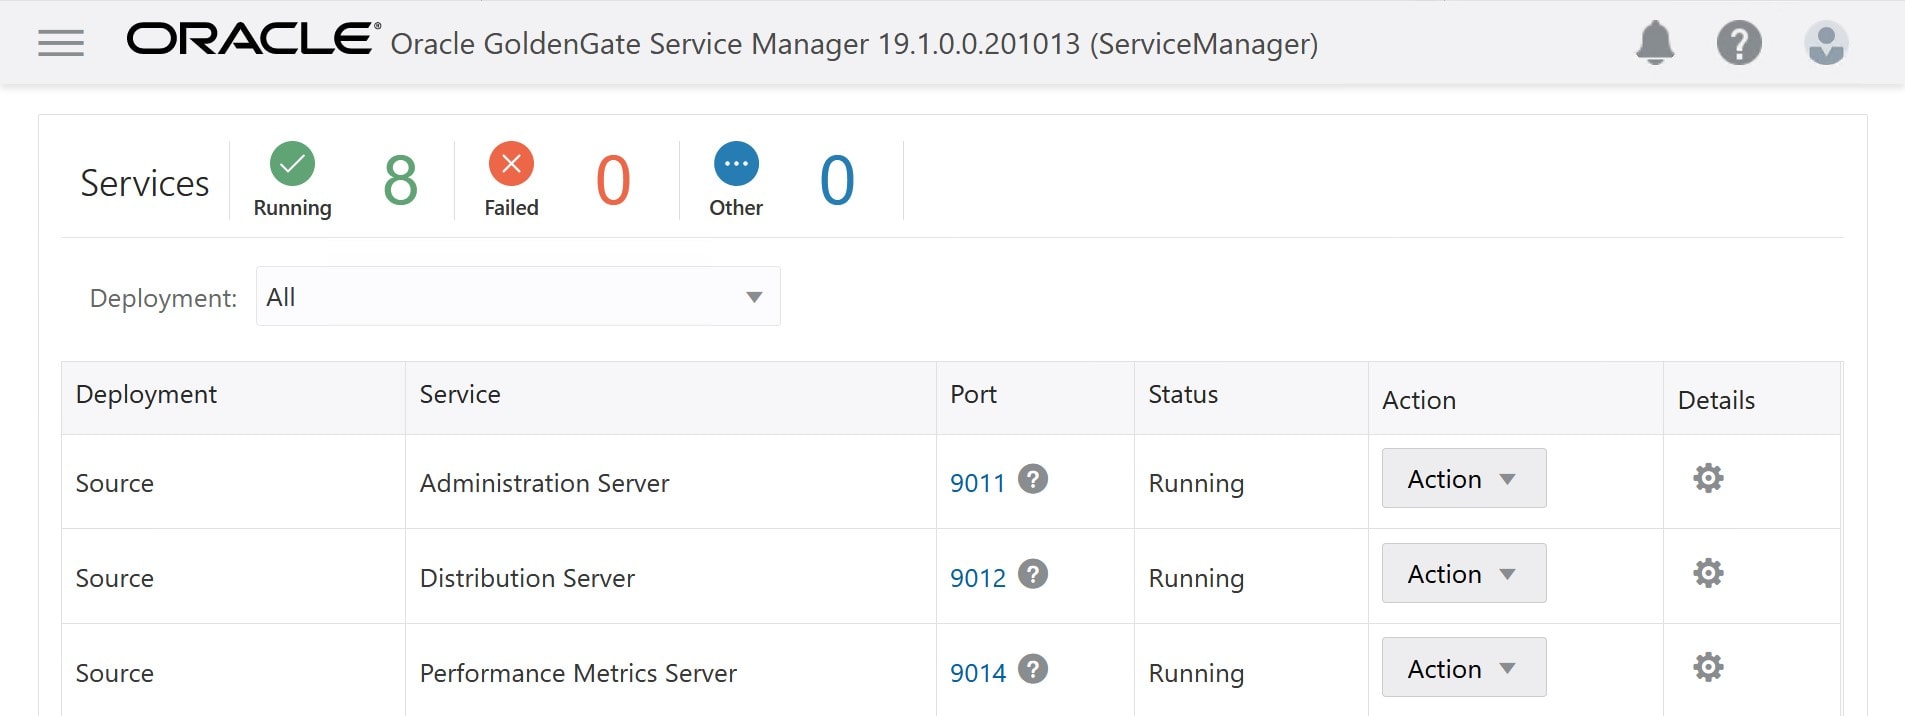
Once logged in you can ensure that all the services are up and running. Most important are the Administration Server services – on source and target. They are handling the replication. Ensure all services are running You can start and stop the services from the Action drop-down menu.

By clicking on the Port number of each of the services, you can go to the specific console for each of the services. Again, the Administration Server are the ones of interest. Click on the port number to go to the specific console

Monitor Extract

If you followed the link to the Source Administration Server (by clicking on the port number) you end up here: Administration Server overview

Ensure that the extract is running. Further down the page you see a list of events. From the Action drop-down menu, you can start and stop the extract. And you get into the Details as well: Follow the Details link

You can get a lot of details, like extract statistics. Here you can see that extract has caught one insert into the table locations: Extract statistics

Monitor Replicat

Now you have monitored the extract, and you should also monitor the replication, which is handled by the replicat process. Basically, you do the same as with extract but use the link on the target administration server: Follow the link to the target administration server to monitor the replicat process

Here you should look at the replicat process and ensure that it is running: Ensure replicat process is running

You start and stop the services and get into the details like described above.

Troubleshooting

Here is an example of an error. I have created a table in my source database that does not exist in the target. This break the replication. I can use the list of critical events to figure out what went wrong: Replicat failed

Also, if you go into the details of the replicat process, and switch to the report tab, you can find even more details:

You can also find more logs on the GoldenGate host in the directories:

  • /u02/deployments/Source/etc/conf/ogg/
  • /u02/deployments/Target/etc/conf/ogg/

Conclusion

With Oracle GoldenGate Microservices Architecture it is easy to get an overview of the replication process. There are nice graphical overviews and you can even get detailed information and statistics.

Other Blog Posts in This Series

Zero Downtime Migration – Logical Online Migration

You can migrate a database with Zero Downtime Migration (ZDM) using the Logical Online method. The migration will happen with a combination of Data Pump and Oracle GoldenGate. This way even very large databases can be migrated with very little downtime.

In the introduction blog post I covered the basic characteristics of this approach and explained that Oracle GoldenGate can be used at no extra license cost and it is really simple to use.

Migrate your Oracle Database with Zero Downtime Migration ZDM using Data Pump and GoldenGate

With the Logical Online method, you can even target Autonomous Databases. Both Oracle Autonomous Transaction Processing (ATP) and Oracle Autonomous Data Warehouse (ADW) and also shared and dedicated. When you target an Autonomous Database, you don’t have access to the underlying database host, so instead of SSH access, ZDM will require SQL*Net connectivity.

Benefits

  • First and most important, you don’t need a license for Oracle GoldenGate to use this approach. Yes, that’s right! You are allowed to use a marketplace edition of Oracle GoldenGate 19c for 183 days to migrate your database with ZDM.

Oracle GoldenGate for Oracle – Database Migrations can be used for 183 days to perform migrations into Oracle databases located in Oracle Cloud Infrastructure using the following tools: Oracle Zero Downtime Migration and Oracle Cloud Infrastructure Database Migration

  • Even if you don’t have any GoldenGate experience, you can still use this approach. For example, you don’t need to install and configure GoldenGate yourself. The marketplace image creates the GoldenGate installation for you. Afterwards, ZDM configures GoldenGate and will eventually clean up as well.
  • You can migrate directly into a higher release. For example, if your source database is 12.1.0.2, you can migrate into 19c directly. This avoids the extra downtime normally needed to perform an upgrade.
  • You can migrate directly into a PDB. For example, if you source database is a non-CDB, you can migrate directly into a PDB. This avoids the extra downtime normally needed to convert the database into a PDB using the script noncdb_to_pdb.sql.
  • You can use the full power of Data Pump and GoldenGate to transform your data. By default, ZDM will convert any old BasicFile LOBs into SecureFile LOBs during import. But you can apply other transformations as well. You can partition the table in the target database, you can change the tablespace layout, you can apply compression and anything else that is possible with Data Pump.
  • You can migrate into a different character set (Data Pump and GoldenGate restrictions apply).
  • Your Data Pump export is automatically compressed if the source database is Enterprise Edition. Normally, Data Pump compression would require a license for the Advanced Compression Option. But when you migrate with ZDM to OCI, Oracle allows you to use Data Pump compression without having the Advanced Compression Option.
  • Your Data Pump export is automatically encrypted if the source database is Enterprise Edition. Normally, Data Pump encryption would require a license for the Advanced Security Option. But when you migrate with ZDM to OCI, Oracle allows you to use Data Pump encryption without having the Advanced Security Option.
  • You get recommendations on the migration before it is actually started. ZDM includes the Cloud Premigration Advisor Tool (CPAT) which analyzes your database and give you specific recommendations that matches the target database. For example, if you target an Autonomous Database, CPAT will warn if you have unsupported objects.
  • You can migrate a SE2 database into OCI using this approach as well.
  • You can build your target database in advance and configure backup upfront as well. You can test your backup/recovery strategy before you complete the migration.
  • You can build a standby database in advance as well. Your new OCI target database can be protected by Data Guard from the very second you perform the switch-over. I would recommend doing the initial Data Pump load first, and then build the standby database. This ensures that a minimum of changes has to be applied via redo.

Considerations

  • The time zone file in the OCI target database must be higher than that in the source database. Typically, this is not a problem if you provision a brand-new DB System. But if you plan to use an existing CDB in OCI do check the time zone file upfront:
SQL> select * from v$timezone_file;
  • In My Oracle Support you can find a list of recommended patches to apply on the source database when using Oracle GoldenGate. There is one for 11g and one for 12c and newer. You don’t have to apply those patches, but it is a recommendation. However, if you run into issues, you potentially have to patch your source database.
  • Most databases can be migrated with Oracle GoldenGate. Only very exotic data types are not supported. Be sure to check the documentation.
  • When you use Data Pump to migrate you will lose a lot of the information that is stored in the data dictionary, like
    • AWR
    • SQL Plan Baselines
    • SQL Profiles
    • SQL Patches
  • You can still transfer that information, but you need to use other tools. If this is relevant to you, I suggest that you watch our webinar Performance Stability, Tips and Tricks and Underscores where it is covered in detail.
  • Depending on whether you use a full or schema mode export you need to take care of your public objects afterwards. It could be synonyms or database links.
  • For a huge database you should be prepared for the time it takes to perform the Data Pump export and import. No need to worry too much because GoldenGate will keep track of the changes. But for a 100 TB database you should not start the job the day before the switchover is supposed to take place.
  • It is not recommended to execute DDL statements when GoldenGate is replicating changes. The extract and replicat processes that are created by GoldenGate does not replicate DDL statements. If you for example add a table after the initial Data Pump load, it will not get replicated by GoldenGate. However, GoldeGate is a very powerful tool and you can configure it to replicate DDL as well. But you will need to adjust the GoldenGate user privileges and change the parameter files. In the documentation you can read more about the possibilities of DDL replication and how to configure it.

Fallback

Using this approach there is no straight forward way of falling back to the source on-prem database. You could use GoldenGate to reverse the replication when you switch over to the OCI target database. However, it is not configured automatically by ZDM. So, this is very you would need to know GoldenGate and do the required configuration.

Conclusion

You get a lot more options when you use the Logical Online method to migrate your database. Especially, the possibility of migrating directly into a higher release or into a PDB is very attractive. Plus, you can use GoldenGate during the migration at no extra license cost.

However, the flexibility comes at a cost. There is a little more configuration and it is not as straight-forward as the Physical Online method. But it is not complicated.

Want to Know More

If you want to know more about using Data Pump and GoldenGate for database migrations, I suggest that you take a look at our webinar Migration Strategies – Insights, Tips and Secrets

In addition, these links contain additional useful information:

Other Blog Posts in This Series

Zero Downtime Migration – Create GoldenGate Hub

The Logical Online migration method in Zero Downtime Migration (ZDM) uses Oracle GoldenGate to keep the Oracle Database in OCI in sync until you perform the switchover. You need an Oracle GoldenGate Hub to do that and you should use the deployment from the OCI Marketplace. Let’s do it!

  1. First, go to the OCI Marketplace and search for goldengate for oracle. You should use the image called Oracle GoldenGate for Oracle – Database Migrations. Use the OCI Marketplace to find the Oracle GoldenGate application

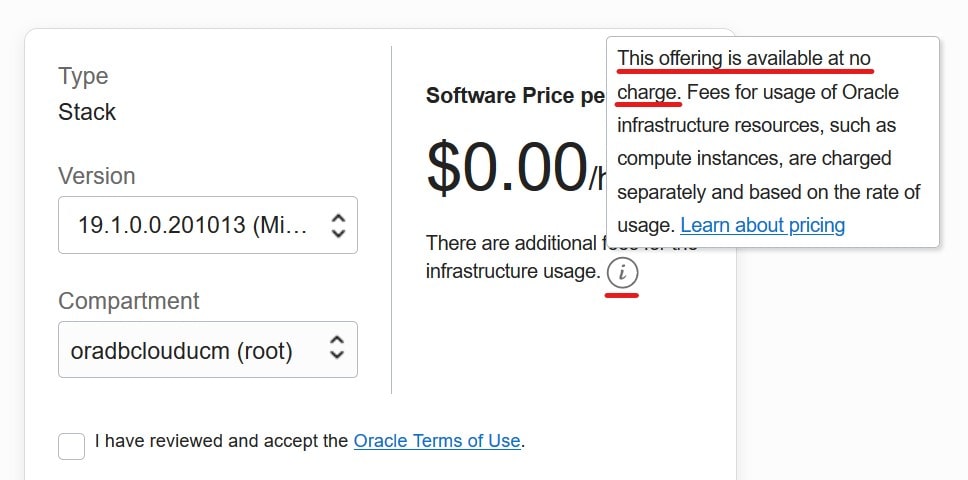
  2. On the application page you can verify that the software is free but you still have to pay for the underlying infrastructure, like the compute instance. In addition, certain terms apply:

Oracle GoldenGate for Oracle – Database Migrations can be used for 183 days to perform migrations into Oracle databases located in Oracle Cloud Infrastructure using the following tools: Oracle Zero Downtime Migration and Oracle Cloud Infrastructure Database Migration

  1. When you hit Get App button you need to log in to OCI. Be sure to select the right region and compartment. Again, you can verify that the software is free – but you pay for the compute instance. Hit Launch Stack. Launching an Oracle GoldenGate stack using OCI Marketplace This version of Oracle GoldenGate is available for free but you have to pay for the underlying infrastructure

  2. On the next page Create Stack – Stack Information simply give it a name. I call it OGG4DEMO.

  3. On the next page Create Stack – Configure Variables you fill in additional information like network, your SSH public key etc. But most important – you also need to specify the Oracle Database version of the source and target database – and whether the target database is an Autonomous Database. Don’t worry about the deployment names they are good as they are. Even if the target attributes are listed as optional – fill them out. Pick the right database versions for the source and target database

  4. Review the settings and hit Create. The stack is now being deployed. The stack is deploying and very soon it will be ready

  5. Now, head on over to Compute and Instances to find the newly created compute instance with Oracle GoldenGate already installed. Depending on your network settings use either the public or private IP address or the computer name (DNS). When the stack has been created, you can find it in Compute > Instances

  6. Use the IP address (or computer name) and your SSH key to connect to the server as opc. There is a file called ogg-credentials.json which contains the username and password that is needed to connect to the Oracle GoldenGate Hub In ogg-credentials.json you find the username and password required to connect to the Oracle GoldenGate Hub

  7. Now you can connect via HTTPS (https://193.122.52.34) to the Oracle GoldenGate Hub. Use the credentials from ogg-credentials.json and log in. That’s it – your very own Oracle GoldenGate deployment. The landing page when you log in to the Oracle GoldenGate Hub

Other Blog Posts in This Series

Appendix

A. The very last thing is to apply the latest patches to Oracle GoldenGate. But that will be a topic for a future post.

B. When you connect to Oracle GoldenGate via HTTPS, you will probably get a security warning in your browser. The initial deployment comes with a self-signed certificate which alerts many browsers. Follow the procedures in your organization to deploy a proper certificate. Read more about Securing the Microservices Architecture.

C. The credentials for Oracle GoldenGate are case sensitive. It applies to the password but also the username (oggadmin, not OGGADMIN).

DataPump Export from Data Guard

Exporting data from your production database can be a pain for several reasons:

  • You probably want a consistent export so you set the Data Pump parameter FLASHBACK_TIME. That requires a lot of undo space. If there is heavy activity on the database, then you risk running into ORA-01555.
  • You want export the data quickly using the parallel options in Data Pump. The quicker you export, the less susceptible you also are to ORA-01555. But parallel uses more resources.

If you have an Active Data Guard, you can export your data from the standby database. It should be straightforward, right? An export is after all just reading data…

But Data Pump is not just a simple export tool. It is quite advanced – and to support all that functionality it does require a master table to be created which can be used to coordinate the operation. Further, it uses Advanced Queueing (AQ) for communicating between the processes. And AQ also requires a writable database.

But how about DML Redirect that was introduced in Oracle Database 19c? Can it be used to handle those few DMLs? No, because creation of the master table is a DDL – not a DML. If you try, you will fail:

$  expdp system@localhost:1521/pdb1 schemas=SH directory=mydir

Export: Release 19.0.0.0.0 - Production on Mon Apr 12 18:19:22 2021
Version 19.10.0.0.0

Copyright (c) 1982, 2019, Oracle and/or its affiliates.  All rights reserved.

Password:

Connected to: Oracle Database 19c EE Extreme Perf Release 19.0.0.0.0 - Production
ORA-31626: job does not exist
ORA-31633: unable to create master table "SYSTEM.SYS_EXPORT_SCHEMA_05"
ORA-06512: at "SYS.DBMS_SYS_ERROR", line 95
ORA-06512: at "SYS.KUPV$FT", line 1163
ORA-16000: database or pluggable database open for read-only access
ORA-06512: at "SYS.KUPV$FT", line 1056
ORA-06512: at "SYS.KUPV$FT", line 1044

Solution

I turned on my bat signal and got help from my fellow Product Manager, Pieter Van Puymbroeck. I turned on the bat signal and got help Photo by Ali Kokab on Unsplash

Use a snapshot standby, he said. Of course – Snapshot Standby is part of Enterprise Edition, so if you have Data Guard, you also have Snapshot Standby. If you need a quick recap on what a snapshot standby database is, you should check out this video.

First, I convert my physical standby database (named CDB19_fra3zt) into a snapshot standby database:

DGMGRL> convert database 'CDB19_fra3zt' to snapshot standby;

Next, create a directory object that can be used with Data Pump:

SQL> create directory mydir as '/tmp';

Finally, start an export. Notice that I haven’t set FLASHBACK_TIME. When exporting from a snapshot standby there are probably no other users on the database, so you don’t need to worry about consistency of the export:

$ expdp system schemas=sales directory=mydir

My data has now been exported, and it is time to convert my snapshot standby database back into a physical standby database to properly protect my precious database:

DGMGRL> convert database 'CDB19_fra3zt' to physical standby;

But

Will this jeopardize my primary database. No, but ….

Your primary database is still protected, because log files are still sent to the standby database, but not applied. What will then happen if I need to switch over or fail over?

  1. Convert the snapshot standby database back into a physical standby database
  2. That will implicitly issue a Flashback Database and revert all the changes made
  3. Then catch up with the primary by applying all the log files
  4. Finally, complete the switchover or failover

Bottomline, it will take longer! The flashback operation is really fast and should be done within minutes. After all, Data Pump isn’t making that many changes. Only the master table and some AQ stuff. How much time then to do log apply? That depends entirely on how big the apply lag is.

So, if you choose to go down this path be prepared that in the event of a switchover or a failover, it will take a little longer until the standby is open for business. Unless, you have two standby databases, then you will still have run ready to jump in immediately.

GoldenGate

If you need the Data Pump export to perform an initial load for GoldenGate, then you might want to control the SCN at which the export is happening. If so, cancel redo apply on the standby database and roll forward to the desired SCN:

alter database recover managed standby database cancel;
alter database recover managed standby database until change n;

Before converting the standby database to snapshot standby:

alter database convert to snapshot standby;

Later on, when you need to start replication in GoldenGate you can use the following option:

START REPLICAT ATCSN n

It Must Be From Physical Standby

On Twitter I was made aware that AWS RDS does not allow snapshot standby. The user referred to a MOS note describing how to export from a physical standby database. You need a proxy database and a database link. You find the details in How To Use DataPump Export (EXPDP) To Export From Physical Standby Database (Doc ID 1356592.1).

I recommend using this method only as a last resort. It is more cumbersome and you don’t get the same performance as via a snapshot standby database. Using Data Pump over a database link limits certain parallel capabilities.

Conclusion

You can export from your Data Guard, if you convert it temporarily to a snapshot standby. Be prepared that a switchover or failover operation will take longer.

If you want to know more about Data Pump, you should check out our webinar Migration Strategies – Insights, Tips and Secrets.

And finally, speaking of Data Pump, remember to get the Data Pump bundle patch (bug 32551008) as Roy mentioned on Twitter.

Future-proof Your Encrypted Database During Upgrade

In Oracle Database 19c, use of sqlnet.ora to define the keystore (or wallet) location has been deprecated. Instead you should use the database parameter WALLET_ROOT. If you upgrade to Oracle Database 19c with AutoUpgrade, it has become a lot easier. Let AutoUpgrade do the work for you.

How To

If you instruct AutoUpgrade to use the new encryption parameters it will not only add the parameters to the SPFile but also copy the keystore file to the location defined. This is what you have to do:

  1. Create a text file which contains the definition of WALLET_ROOT and TDE_CONFIGURATION. I call it /tmp/au-pfile-tde. Optionally, change the location of the keystore to fit your organization.
WALLET_ROOT='/etc/oracle/keystores/$ORACLE_SID'
TDE_CONFIGURATION='KEYSTORE_CONFIGURATION=FILE'
  1. Instruct AutoUpgrade to add those parameter during and after upgrade. Add the following to your AutoUpgrade config file:
upg1.add_during_upgrade_pfile=/tmp/au-pfile-tde
upg1.add_after_upgrade_pfile=/tmp/au-pfile-tde

That’s it! AutoUpgrade will detect that you are changing the keystore location, and it will copy the keystore files to the new location at the appropriate time.

Important

  • When you use WALLET_ROOT the keystore files should always be stored in a subfolder called tde. This means that the keystore files will end up in /etc/oracle/keystores/$ORACLE_SID/tde. You should not add /tde manually to WALLET_ROOT. The database will do that automatically when it looks up the keystore.
  • If you want to move the keystore into ASM, there is a special procedure that you must follow. AutoUpgrade can’t do that for you. Check How To Migrate TDE Wallet From Local OS File System to ASM ? (Doc ID 2369614.1).

Now What

Since you have moved the keystore files to a new location there are some things that you should take care of:

  • You can remove the sqlnet.ora parameter ENCRYPTION_WALLET_LOCATION. It is not used anymore.
  • The keystore files that were stored in the old location (that defined by ENCRYPTION_WALLET_LOCATION) can be moved manually to a backup location. I would never recommend that you delete keystore files – NEVER! Instead move the old files to a backup location and keep them there.
  • The keystore files are to be considered critical and contain sensitive information, so ensure that the new location has the same security measures as the old one – like:
    • Restricted file permissions
    • Auditing
    • Backup

Background

Traditionally, if you have an encrypted database, you need to define the keystore location in sqlnet.ora using the parameter ENCRYPTION_WALLET_LOCATION. You would set it to something like this:

ENCRYPTION_WALLET_LOCATION=
 (SOURCE=
  (METHOD=FILE)
   (METHOD_DATA=
    (DIRECTORY=/etc/oracle/keystores/$ORACLE_SID)))

For many reasons, sqlnet.ora was not a good location for this parameter, and especially with the introduction of isolated keystore mode, a new method was needed.

In came WALLET_ROOT and TDE_CONFIGURATION database initialization parameters. The former, WALLET_ROOT, defines the location of the keystore. The latter, TDE_CONFIGURATION, defines which kind of keystore is in use. Typically, it is set to FILE – that’s when you use a software keystore (a file in the OS). But it could also be OKV if you are Oracle Key Vault. For a software keystore you would set it to something like:

ALTER SYSTEM SET WALLET_ROOT='/etc/oracle/keystores/$ORACLE_SID' SCOPE=SPFILE;
ALTER SYSTEM SET TDE_CONFIGURATION='KEYSTORE_CONFIGURATION=FILE' SCOPE=SPFILE;
SHUTDOWN IMMEDIATE
STARTUP

Now, the database finds the keystore location using the WALLET_ROOT parameter which is much more smooth.

As of Oracle Database 19c, configuration the keystore using sqlnet.ora has been deprecated, and as with any other deprecated functionality, you should move to a fully supported alternative.

Further Reading

Other Blog Posts in This Series

Performance Stability after Upgrade and Migration

Yesterday I gave a talk to the Danish Oracle User Group. The topic was Performance stability after upgrade and migration and included something about statistics, a lot about SQL Plan Management and a few recommendations for parameters in Oracle Database 19c.

Danish Oracle User Group

If you are interested you can download the slides and have a look yourself. The talk itself was not recorded.

You Want More?

The content I presented is part of a revamped webinar that Roy, Mike and I are giving on Thursday, 4 March 2021 at 19:00 CET. We call it

Performance Stability, Tips, Tricks & Underscores

> The third webinar the series addresses performance stability, tips, tricks and underscores. Participants learn how to perform proactive testing before upgrading to Oracle Database19c. > >Topics that will be covered during this session: > >* Testing Principles >* Ensure Performance Stability >* SQL Plan Management >* Real Application Testing >* Tips, Tricks & Underscores to get the best out of Oracle Database 19c

It is all tech – no buzzwords and marketing. We have to keep it within two hours, but I think that we already have way too much content. I assure you it will be action packed.

If that sounds interesting, sign up and I will see you next Thursday. It will be so much fun.

Otherwise, you can find the recording a few days after. In addition, most of the content will also be cut into bite-size pieces and uploaded to our YouTube channel – why not subscribe?

Links

Upgrade Internals – Webinar

Here is a little teaser for our upcoming webinar on Database Upgrade Internals – and so much more on Wednesday 10 February 2021 at 10:00 CET. You can still sign up.

Virtual Classroom Series - Upgrade to Oracle Database 19c

We have a special guest star joining, Frederick Alvarez – one of the masterminds behind AutoUpgrade. In addition, as usual Mike Dietrich will be there, and we have prepared a whole lot of new contents for this webinar. And – if I have to say so myself – it has become quite good and interesting. If you are still not convinced take a look at this!

What Actually Happens During Upgrade

We will go into the upgrade itself, dissect it, and discover what actually happens. Hopefully, it will no longer be a black box to you.

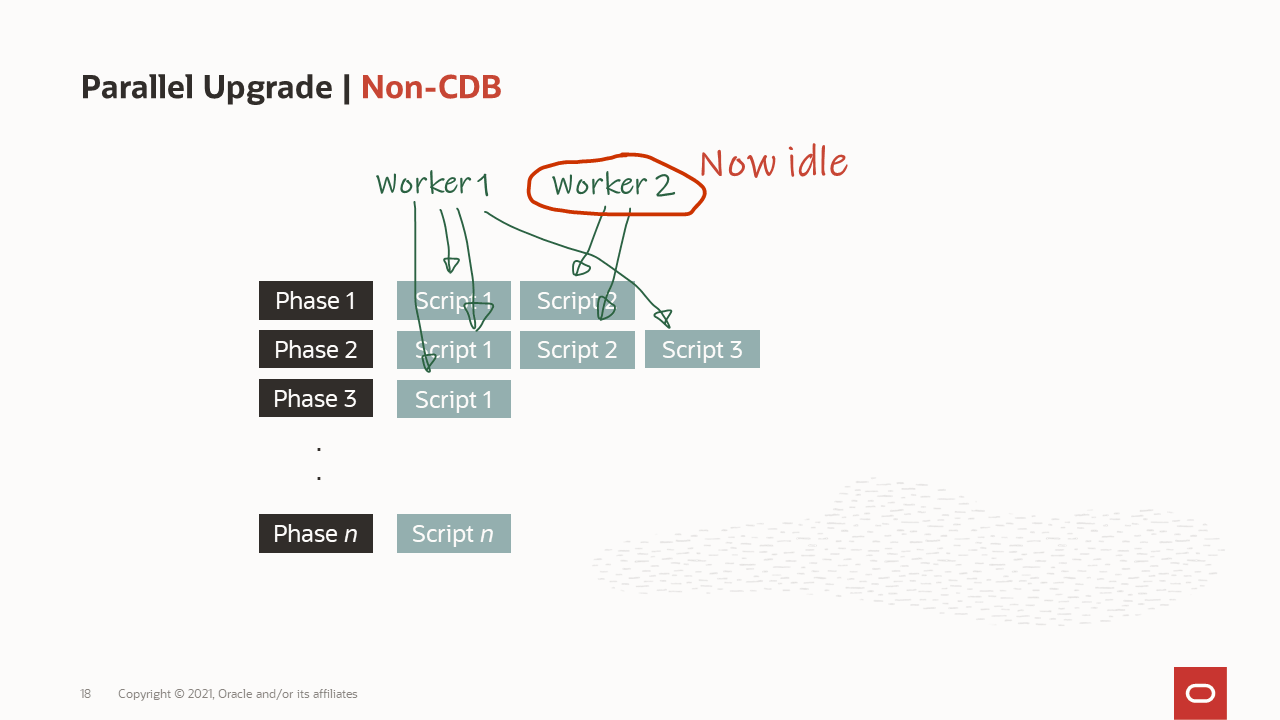
How are the workers processing the upgrade? How are the workers processing the upgrade?

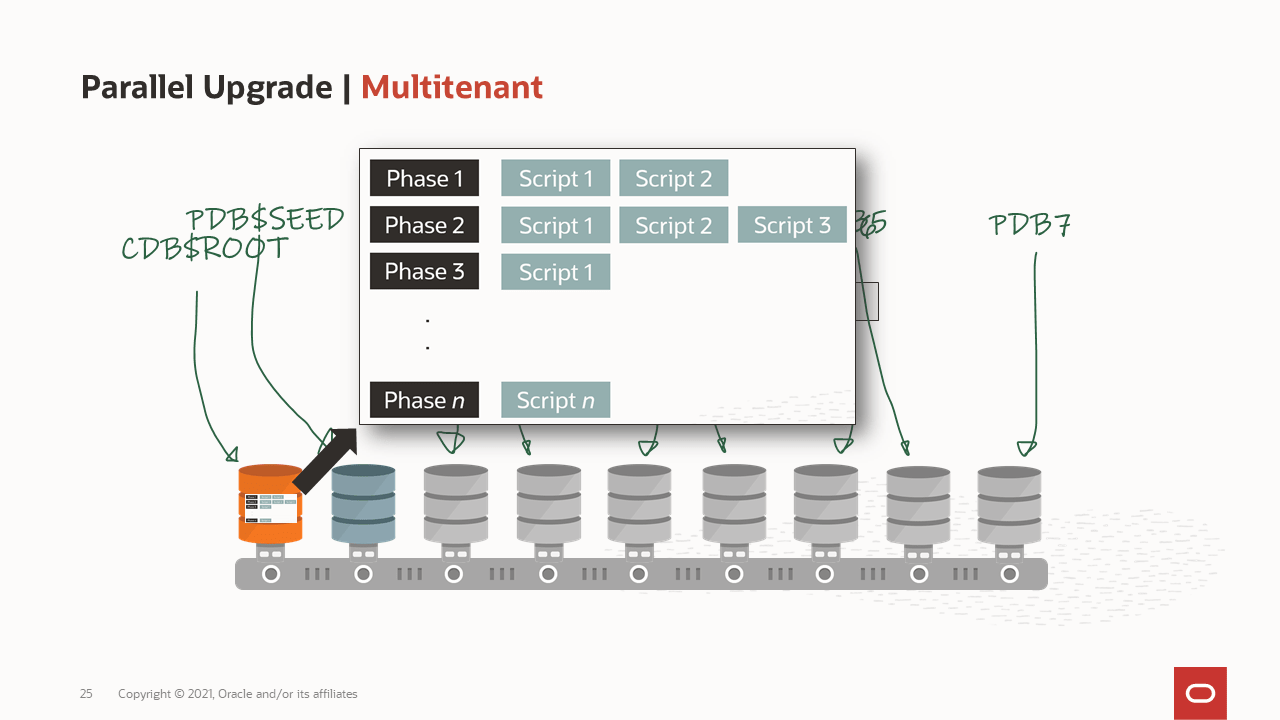
How is a container database upgraded? How is a container database upgraded?

What goes on in the phases of the upgrade? What goes on in the phases of the upgrade?

I Need More Power, Scotty

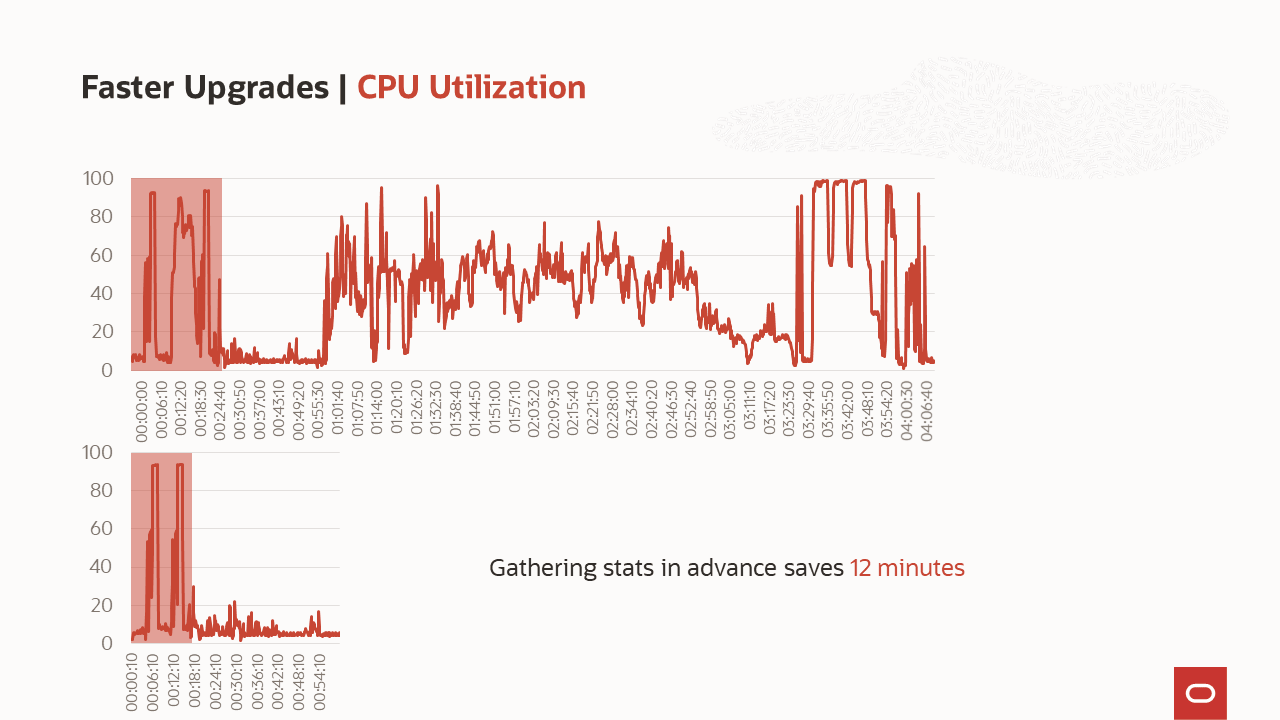
We will also cover, how you can make your upgrade faster and show what you can achieve.

What is the benefit of gathering stats before the upgrade? What is the benefit of gathering stats before the upgrade?

What Can You Achieve With AutoUpgrade

A deep dive into the checks that are executed by AutoUpgrade. A list of some of the comprehensive checks that are executed by AutoUpgrade A list of some of the comprehensive checks that are executed by AutoUpgrade

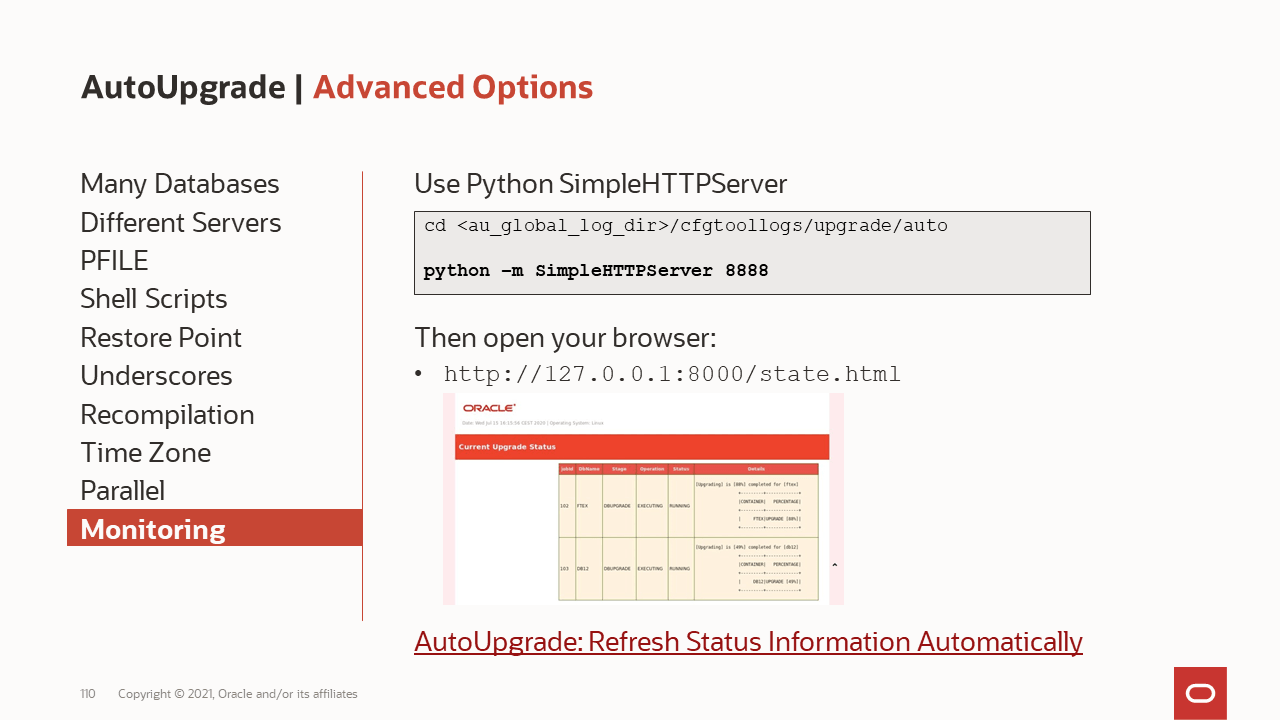
One page monitoring One page monitoring

The Old Releases

For those of you on very old releases, we will discuss how you can upgrade to Oracle Database 19c.

What to consider when doing upgrades from very old releases What to consider when doing upgrades from very old releases

See You

Once the webinar is over we will publish a recording and make the slides available for download.

See you on wednesday!

Control Upgrade Parallelism In AutoUpgrade

Under the hood, AutoUpgrade uses the Parallel Upgrade Utility or catctl.pl to do the database upgrade. The Parallel Upgrade Utility has a long list of options that you can configure. The parallel options being the most notable. In your AutoUpgrade config file you can now specify a subset of options to catctl.pl using the parameter catctl_options.

Now, you should not expect a 10x improvement by adding a ton of CPUs to your upgrade. Mike Dietrich posted a really good article that explains what matters to an upgrade when it comes to performance. But f you want to squeeze out the very last resources on your system during upgrade, or want to fine-tune the distribution of CPUs the resource consumption, you can do it with AutoUpgrade.

How

First, you can find a list of catctl parameters in the documentation.

When you have determined the parameters that you want to use, specify them in your config file either globally (for all upgrades):

global.catctl_options=-N 8

or locally for a specific upgrade:

upg1.catctl_options=-N 8

The above examples will run the upgrade of PDBs using eight parallel processes.

You should have a look in the documentation to know the minimum and maximum values for the settings. At least for the parallel settings it is really good to know.

Non-CDB

Support for this parameter and non-CDB databases was added in 21.1.2. To ensure that the upgrade runs with as many parallel processes as possible:

upg1.catctl_options=-n 8

CDB and PDB

When you upgrade a CDB the following happen:

  • First, CDB$ROOT is upgraded using eight parallel processes.
  • Next, a number of PDBs are upgraded concurrently, starting with PDB$SEED. The total number of parallel processes to use is controlled by the parameter n.
  • Each individual PDB is upgraded using a number of SQL processes as well. This is controlled by the parameter N.

This means that the number of PDBs that are upgraded at the same time is: n / N

What is the best value of n?

  • If you are conservative you set n to CPU_COUNT.
  • If you are bold, you could probably raise it further, because some of the phases in the upgrade runs serially or doesn’t use the full parallel capacity. Try to set n to CPU_COUNT + 10 % and see how loaded your CPUs get. Keep increasing until you find a suitable level.

In the documentation there are some really good examples and explanations of using N and n together.

On a system with CPU_COUNT=48, put the following in your AutoUpgrade config file to run 6 PDB upgrades concurrently using 8 parallel processes:

upg1.catctl_options=-n 48 -N 8

Note, regardless of what you specify, when it comes to CDB$ROOT AutoUpgrade will always run with the maximum number of parallel processes. CDB$ROOT is special and it must be upgraded before any of the other ones can start. Hence, it makes sense to get it completed as fast as possible.

If you are doing an unplug-plug upgrade of a single PDB it could be a good idea to add more parallel processes to that single upgrade. If you want to use 8 parallel processes:

upg1.catctl_options=-N 8

Conclusion

It can be useful to override the default parallel settings during upgrades. You should not expect a 10x performance improvement, but you might squeeze out the very last resources. What is the best setting? It depends. You should go with the defaults, or test it using your own databases.

History

12 April 2021: Added information about support of non-CDB databases as of AutoUpgrade 21.1.2.

Follow-up On Cool Features Webinar – Jan 2021

Wow! Mike and I gave a webinar yesterday: Cool Features – not only for DBAs. We showed a lot of cool features – and the audience recognised that by asking really cool questions. We had more than 100 questions to answer live, and below you can find the answer to those questions that we had to investigate further.

But first a few practical remarks:

Virtual Classroom Series - Upgrade to Oracle Database 19c

Expression Based Parameters

Ahh – one of my new favourites. A viewer asked whether there is any syntax check when you make an expression based parameter. So lets try. First command should work:

SQL> alter session set resumable_timeout='3000/2';

Session Altered.

Now, let’s make a syntax error and see what happens:

SQL> alter session set resumable_timeout='3000//2';

ORA-32005: error while parsing size specification [3000//2]

SQL> alter system set resumable_timeout='3000//2';

ORA-32005: error while parsing size specification [3000//2]

SQL> alter system set resumable_timeout='3000//2' scope=both;

ORA-32005: error while parsing size specification [3000//2]

SQL> alter system set resumable_timeout='3000//2' scope=memory;

ORA-32005: error while parsing size specification [3000//2]

SQL> alter system set resumable_timeout='3000//2' scope=spfile;

ORA-32005: error while parsing size specification [3000//2]

Conclusion: Your expressions are checked when you issue the ALTER SESSION or ALTER SYSTEM command.

But take care when using environment variables in your expressions. If the environment variable is available when you issue the statement, the command will succeed. However, if the environment variable is not present when the database restarts, then you will have a problem. This could be the case if you forget to add the environment variable to your profile or the environment in Grid Infrastructure (srvctl setenv). If this happens, the startup will error out.

And finally, the expressions you put into a pfile are not checked before the database starts using that pfile. If there are invalid expressions in your pfile, the database startup will error out as well.

Online Table Move

Indexes and LOBs

When you move a table online the indexes remain valid during and after the move. Optionally, you can specify the UPDATE INDEXES clause to change the index storage attributes as well (like moving index to a new tablespace):

SQL> alter table t1 move online tablespace data update indexes(i1 tablespace data);

The initial version of blog post claimed that indexes become unusable during online table move unless you specified the UPDATE INDEXES clause. This is not true! Kudos to Olaf Nowatzki for information me. Thanks!

The LOB segments that are created to support the LOB columns remain in the same tablespace, even if you move the table to a new tablespace. But if you want, you can also move the LOB segment as well:

SQL> alter table t1 move online tablespace data lob(c1) store as (tablespace data);

A viewer was concerned whether he could move a table online and also update indexes because one of the indexes was really wide. Apparently, in a previous version this had been an issue to them. I tested this out with an index on 10 columns defined as VARCHAR2(128 BYTE). And this was not a problem. If you index is even wider; test it yourself – or consider whether you really need such an index.

It is supported move an IOT online as well – but not partitioned IOTs.

The Rest

If the table has unused columns when you move it, it will still have unused columns. They are not affected by a move operation. Actually, Connor McDonald made a really good video where he talks about unused columns.

Also, an attendee wanted to know whether the online command generated more UNDO or TEMP. Let’s see what happens with my 125 MB large table (no indexes):

Metric Online move Regular move
undo change vector size 96504 37988
session pga memory 5750416 4243088

As you can see it does require more UNDO to move the table online. But the numbers might change on a busy system with many indexes and LOBs. TEMP appears to be relative unaffected – it might change if I have unique indexes and must rebuild those. Lesson learned – expect more resource usage – test before trying in production.

And finally – does online table move work on tables with OLS (Label Security) policies? I don’t know – so far I haven’t been able to get confirmation. My immediate answer is NO. Take for instance DBMS_REDEFINITION – it is not supported when the table has OLS policies, so I assume the same applies for online table move.

Online Convert To Partitioned Table

This feature only works on a non-partitioned (or regular table). If your table is already partitioned, and you want to change to a different partitioning method, you must use another method (like DBMS_REDEFINITION).

Online Data File Move

When you move a data file online, the database creates an exact copy of the data file in the new location. It is bit-by-bit identifical.

This also means that any free space in the data file is not reclaimed, nor is the High Water Mark affected.

Standby Database Operations

I demoed how the standby database in 19c can do automatic flashback, when the primary database flashes back. A viewer asked whether you can flash back to the same restore point multiple times without the standby database complaining.

My immediate answer was: yes, you can flash back to the same restore point multiple times. The documentation doesn’t mention such a restriction, so I was eager to try it out.

I made a data guard setup in OCI and I was able to flash back to the same restore point three times – and the standby database followed each time.

Gradual Password Rollover

With gradual password rollover a user can temporarily have two passwords. A viewer asked whether you can identify the sessions that are still connecting with the old password. And you can with unified audit trail provided you are auditing logons. In that case simply look at the AUTHENTICATION_TYPE column of the audit entries for LOGON actions:

SQL> select   authentication_type, event_timestamp 
     from     unified_audit_trail 
     where    action_name='LOGON' and dbusername='APP_USER' 
     order by event_timestamp;

Your result will be something like:

authentication_type
(TYPE=(DATABASE));(CLIENT ADDRESS=((PROTOCOL=tcp)(HOST=10.0.1.225)(PORT=24974)));(LOGON_INFO=((VERIFIER=12C-NEW) (CLIENT_CAPABILITIES=O5L_NP,O7L_MR,O8L_LI)));
(TYPE=(DATABASE));(CLIENT ADDRESS=((PROTOCOL=tcp)(HOST=10.0.1.225)(PORT=24983)));(LOGON_INFO=((VERIFIER=12C-OLD) (CLIENT_CAPABILITIES=O5L_NP,O7L_MR,O8L_LI)));

Look at the VERIFIER information. If a user is using the old password in a rollover period, the identifier is suffixed -OLD. Similar, the suffix is -NEW if the new password is used.

This is a very useful addition to gradual password rollover.

Conclusion

Thanks to everyone that participated today. We had so much fun preparing the webinar for you. And really – thanks for all the cool questions. Doing stuff remote is really hard, and you really feel disconnected from the audience. But it helps a lot with good questions.

See you next time.
AutoUpgrade One-liner

You can use AutoUpgrade to upgrade a database using only a single command line. No config file is needed!

Whenever we talk about AutoUpgrade, we also mention the config file. The file that contains information about what has to be upgraded. A very simple version of such a config file could look like this:

upg1.sid=DB12
upg1.source_home=/u01/app/oracle/product/12.2.0.1
upg1.target_home=/u01/app/oracle/product/19

This is the preferred and recommended way of using AutoUpgrade. But you can actually specify everything on the command line.

Upgrade in One Line

By using the command line option config_values you can now specify the config file entries on the command line. Instead of using the above config file you could execute:

java -jar autoupgrade.jar \
   -config_values "sid=DB12,source_home=/u01/app/oracle/product/12.2.0.1,target_home=/u01/app/oracle/product/19" \
   -mode analyze

Notice how I used config_values to specify the contents of the config file. The prefix that you have to use in the config file (in this case upg1) is not used here (only for global entries, like global.autoupg_log_dir).

If you have several databases to upgrade, you separate them with as asterisk (*):

-config_values "sid=DB1,...,*,sid=DB2,...,*,sid=DB3,..."

Using Environment Variables

A few of the config file entries can be specified as environment variables instead:

Config file entry Environment variable
sid $ORACLE_SID
source_home $ORACLE_HOME
target_home $ORACLE_TARGET_HOME
target_version $ORACLE_TARGET_VERSION

So, you can start AutoUpgrade like this as well:

export ORACLE_SID=DB12
export ORACLE_HOME=/u01/app/oracle/product/12.2.0.1
export ORACLE_TARGET_HOME=/u01/app/oracle/product/19
java -jar autoupgrade.jar -config_values -mode analyze

And it works fine on Windows as well. Just use set instead of export.

What Happens

AutoUpgrade first needs to determine the global logging directory (global.autoupg_log_dir).

  • If you specify the global logging directory it will be used.
  • If you do not specify the global logging directory one of the following will be used:
    • Linux/Unix: /tmp/autoupgrade
    • Windows: C:\Users\name\AppData\Local\Temp\autoupgrade

Next, AutoUpgrade will create a config file using the information supplied either using config_values or from the environment.

From here on AutoUpgrade behaves as usual.

Conclusion

If needed, you can provide all input to AutoUpgrade in one command line. This is useful if you are using AutoUpgrade in scripts or from Ansible or similar orchestration tools.

I would still recommend the use of a config file. It is easier to read and write the options in a nice formatted text file. Further, you avoid the potential trouble of escaping characters on the command line. And, finally, you avoid having a very long an unreadable command line. These arguments are, by the way, the same we use when we recommend using a parameter file (.par) for Data Pump.

Further Reading